Crypto
27 Sep 2026
Read 12 min
How to fix third-party timeout error and restore services *
Fix third-party timeout error by increasing timeout values to restore reliable external responses.
Slow or failing API calls often come from upstream delays. To fix third-party timeout error fast, check if the vendor is down, increase the temporary timeout, retry with backoff, and narrow the request. Then add caching, circuit breakers, and better timeouts. These steps restore services now and prevent the same outage next time.
Third-party timeouts hurt users and revenue. A page hangs. A checkout fails. A webhook never returns. The good news: you can restore service quickly and make your system stronger. This guide shows what a timeout means, how to get back online fast, and how to prevent repeat incidents with small, clear changes.
Vendor outage or high load
Large payloads, wide filters, or missing indexes on the vendor side
Slow DNS or TLS handshake
Short client timeout settings that do not match real latency
Network congestion or blocked regions
Time budgets matter. If a page needs three API calls and each call has a 5-second timeout, you may blow past your page budget. You must set timeouts with the whole user flow in mind.
Ping a light endpoint (like /health or /ping)
Test from two regions or ISPs
Check if only one API path is slow
Raise the timeout by a safe amount (e.g., from 5s to 15–30s)
Set a clear rollback time window
Document the change in your incident log
Retry 2–3 times with backoff (e.g., 200ms, 500ms, 1s) + random jitter
Stop retrying for 4xx errors that will not change
Request only needed fields
Use page size limits (like 50–100 items)
Send compressed JSON (gzip/br)
Serve cached prices or profiles for a short time
Queue non-critical writes for async processing
Page budget: 2–3 seconds for first response
API calls: under 1 second typical, hard cap 3–5 seconds
Global guardrail: cancel all work past your SLO
Make timeouts visible in config. Avoid “infinite” waits. Align keep-alive and idle timeouts so they do not fight each other.
Enable HTTP keep-alive and connection pooling
Prefer HTTP/2 or HTTP/3 if the vendor supports it
Tune DNS caching and verify TLS certificate chains
Use ETag/If-None-Match or Last-Modified
Honor Cache-Control headers
Cache-by-key for common queries
Warm the cache on deploys or traffic spikes
Put long writes or reports into a queue
Return a job ID and show progress
Retry jobs with backoff and dead-letter queues
Cap concurrent calls per service
Batch small reads when safe
Honor Retry-After headers and vendor quotas
Open the circuit after a threshold of failures
Serve a fallback while open
Half-open with a few test calls before closing
Use field masks (select columns)
Filter early and sort by indexed fields
Compress payloads and avoid large blobs
Use idempotency keys for safe retries on writes
Use two DNS resolvers
Set short but safe TTLs
Test routes with traceroute or mtr
Consider a private link or peering for high-traffic partners
Reproduce with a tiny, known-good request
Capture request IDs, timestamps, and regions
Compare latency percentiles (P50, P95, P99) before vs now
Inspect headers: Retry-After, RateLimit-Remaining, ETag
Check logs for client-side timeouts vs server 5xx codes
Trace across services to find the slow hop
Test from a different region to rule out ISP issues
Ask the vendor for a timeframe and any workarounds
This playbook helps you fix third-party timeout error without guesswork, and it creates artifacts for a later review.
Success rate and timeout rate
Latency P50/P90/P95/P99
Request volume and concurrency
Error breakdown by code and endpoint
Cache hit ratio for read-heavy calls
Set alerts on SLOs, not just on single spikes. Build dashboards per vendor so on-call can see status at a glance.
Cached catalog with “prices may refresh soon”
Deferred receipts for payment webhooks
Local address autocomplete when maps time out
Hide non-critical widgets until the vendor recovers
Users prefer a clear, partial result over a spinning loader.
Mask tokens and PII in logs
Use HTTPS everywhere
Encrypt queued payloads at rest
Use idempotency to avoid double charges
Time window, regions, and request IDs
Exact endpoints and sample payloads
Observed latency and error rates
Any changes you made around the incident
Ask for limits, best practices, and recommended timeouts. Request a sandbox or bulk endpoints if you need to move large data.
What failed first?
Which alert fired?
What worked as a safe fallback?
What will you automate or cache next?
A small list of actions beats a long report.
Strong systems expect slowness and recover fast. With clear timeouts, good retries, and simple fallbacks, you can fix third-party timeout error today and keep services stable tomorrow.
What a timeout means and why it happens
When your app calls another service, it waits for a response. A timeout means the answer took too long. Your client, proxy, or API gateway closes the connection. You might see errors like 500, 502, or 504. Sometimes the vendor is slow. Sometimes your request is too big. Sometimes the network path is the problem. Common causes include:Quick checks to restore service fast
Check the vendor status and scope
Look at the vendor status page and recent incidents. Try a simple health endpoint. Try the same request with smaller filters. If a narrow query works, you found a scope issue.Increase the timeout temporarily
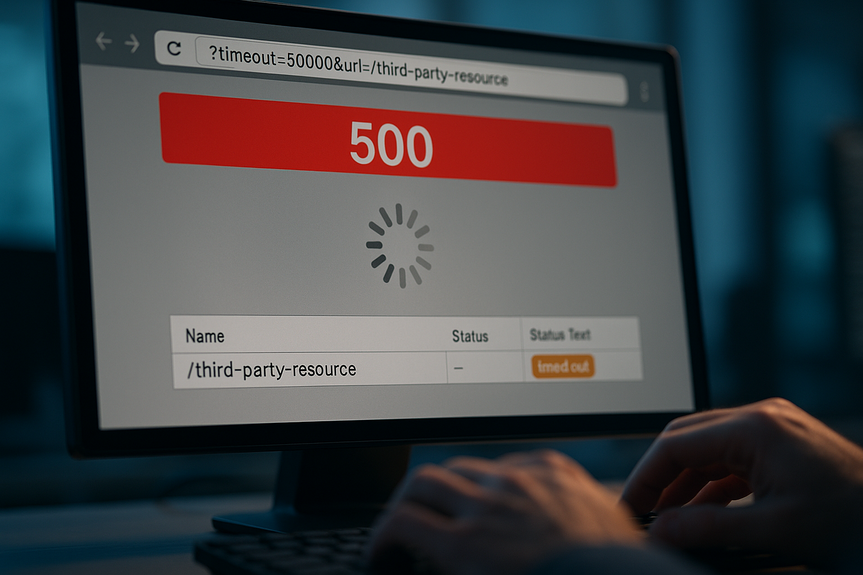
Some services allow a query parameter like timeout=50000 to wait longer. Use this as a short-term fix, not a habit. It can reduce errors while the vendor is slow.Retry with exponential backoff
One spike can cause a timeout. A retry can succeed. Use a small number of retries and add jitter to spread the load.Reduce payload and scope
Ask for less data per call. Split one heavy call into several light calls. Use pagination and selective fields.Switch to a fallback
If you have a cache or a secondary provider, switch. Show cached data with a “refreshed just now” note. For writes, queue the request and confirm later.How to fix third-party timeout error for good
Set clear, layered timeouts
You need timeouts at each layer: client, proxy, server. They should fit your user experience budget.Use connection reuse and modern protocols
Slow setup adds latency. Reuse connections and reduce handshakes.Cache what you can
Many third-party reads do not change fast. Cache them.Move heavy work to async queues
Do not block a user on slow work. Offload it.Limit concurrency and respect rate limits
Too many parallel calls can overwhelm both sides.Apply circuit breakers and timeouts in code
A circuit breaker stops a bad cascade. It trips after many failures and lets the system recover.Make requests efficient
Send only what the vendor needs.Harden DNS and networking
DNS or path issues look like timeouts.Debugging playbook you can run under pressure
Observability that prevents repeats
You cannot improve what you cannot see. Track these for each partner API:Plan for fallbacks and graceful degradation
Decide what the app shows when a partner is slow.Security and safe retries
Do not leak secrets in logs or URLs when you add timeout parameters. Protect user data when you store requests for retries.Work with your vendor
Vendors want solid clients. Share clear data so they can help.Rollback and learn
After the incident, remove the temporary fixes. Return timeouts to normal. Clean up feature flags. Run a short review.For more news: Click Here
FAQ
Q: What does “Request of third-party content timed out” mean?
A: A timeout means the upstream service took too long to respond and the client, proxy, or API gateway closed the connection. You may see 5xx errors such as 500, 502, or 504, and causes include vendor outage, large payloads, DNS/TLS slowness, short client timeouts, or network issues.
Q: What immediate checks should I run to restore service quickly?
A: Check the vendor status page, hit a light health endpoint or a narrowed query, and test from another region or ISP to rule out local path issues. If a narrow request succeeds you can apply a temporary fix such as increasing the timeout or serving cached data while you investigate.
Q: How and when should I temporarily increase timeouts to restore service?
A: Some vendors accept a timeout query parameter (for example ?timeout=50000&url=…), which can be raised for a short-term fix. Raise a safe amount (for example from 5s to 15–30s), set a clear rollback window, and document the change in your incident log to help fix third-party timeout error without creating long-term risk.
Q: What retry strategy should I use to avoid making the outage worse?
A: Use a small number of retries with exponential backoff and jitter (for example 200ms, 500ms, 1s) and avoid retries for 4xx errors that won’t change. This spreads load, improves chances of success, and prevents amplifying spikes.
Q: What architectural changes stop repeat third-party timeouts?
A: Adopt layered timeouts, caching, circuit breakers, connection reuse (HTTP keep-alive or HTTP/2), and move heavy work to async queues to avoid user-facing delays. These measures help fix third-party timeout error for good by preventing cascades and reducing dependency latency.
Q: How can I debug third-party timeouts under pressure during an incident?
A: Reproduce the issue with a tiny, known-good request and capture request IDs, timestamps, and regions to correlate failures. Compare latency percentiles (P50, P95, P99), inspect headers like Retry-After and RateLimit-Remaining, and test from another region to isolate the problem.
Q: How should my app degrade gracefully when a partner API is slow?
A: Prefer a clear partial result over a spinning loader by serving cached data with a “may refresh soon” note and deferring non-critical writes to a queue for later confirmation. Hide non-critical widgets and return job IDs or progress indicators for long-running operations so users see a usable experience instead of a hang.
Q: Which observability metrics and alerts help prevent future timeouts?
A: Track partner metrics such as success and timeout rates, latency P50/P90/P95/P99, request volume and concurrency, error breakdown by endpoint, and cache hit ratio. Set alerts on SLOs and build vendor dashboards so on-call teams can spot and act on degradation before you need to fix third-party timeout error.
* The information provided on this website is based solely on my personal experience, research and technical knowledge. This content should not be construed as investment advice or a recommendation. Any investment decision must be made on the basis of your own independent judgement.
Contents