Crypto
23 Aug 2026
Read 13 min
How to increase third-party request timeout and stop errors *
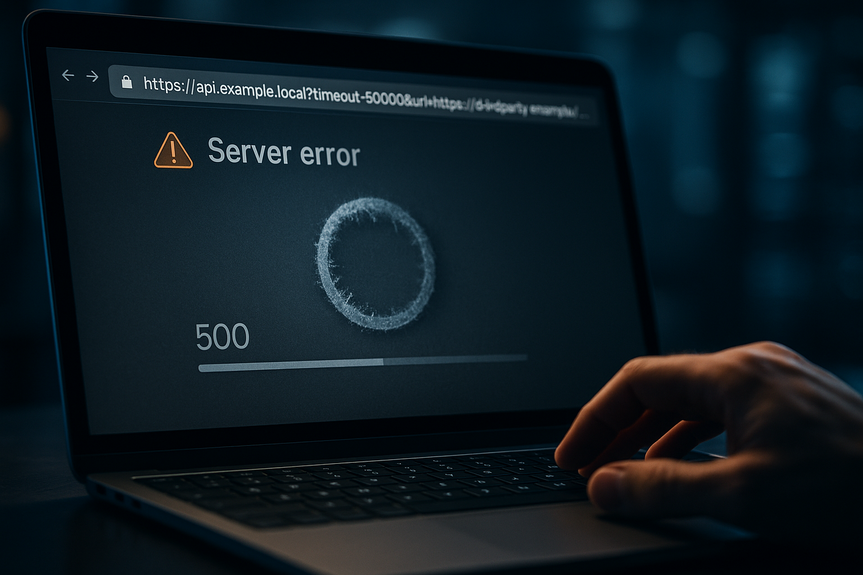
how to increase third-party request timeout and prevent 500 errors using ?timeout=50000&url=/resource
When partner APIs run slow, adjust time limits at the right layer, add safe retries, and watch resource use. This guide shows how to increase third-party request timeout without breaking your app. Learn where to set timeouts, what values to pick, and how to stop 500 errors from timeouts for good.
You saw an error that said a third-party content request timed out and suggested adding a timeout query string in milliseconds. That message is common when a proxy or API wrapper hits its own time cap before the upstream finishes. Raising the limit can help. But you also need guardrails so your app stays fast and stable when the provider is slow.
Your HTTP client (browser, mobile app, server code)
Your server or framework
A reverse proxy or gateway (Nginx, Apache, API Gateway, Cloudflare)
The third-party provider
If any clock hits zero first, the chain fails. One system may return 500. Another may return 504. The message you saw hints that the proxy supports a timeout query parameter like timeout=50000 (50,000 ms). That only changes one clock. You still must check the others so one short limit does not cancel a longer one.
curl: use –connect-timeout 5 and –max-time 20 to cap connect and total time (in seconds).
JavaScript fetch: wrap with AbortController and a timer. For example, abort after 20,000 ms. Also set a total “budget” that covers retries.
Axios: set timeout: 20000 (milliseconds). Add validateStatus and retry logic with backoff.
Mobile SDKs: increase connect and read timeouts to sane defaults (connect 3–5s, read 10–20s).
Tip: Keep a short connect timeout. Long connects tie up sockets even when the host is down.
Node.js: set http(s).request timeouts and AbortController. Tune server.setTimeout (overall response), headersTimeout, and keepAliveTimeout.
Express/Koa: avoid blocking work. Stream responses when possible so proxies see activity and do not think the link is idle.
JVM (OkHttp/Apache HttpClient): set connectTimeout, readTimeout, writeTimeout. Use per-route settings if some partners are slower than others.
Nginx: proxy_connect_timeout (connect), proxy_send_timeout (to upstream), proxy_read_timeout (from upstream). Example values: 5s connect, 60s read for slow partners. Also set client_body_timeout and send_timeout as needed.
Apache: Timeout and ProxyTimeout for upstream work. Start with 60s for reads if you expect slow responses.
HAProxy: tune connect, client, and server timeouts (contimeout, clitimeout, srvtimeout). Use http-keep-alive smartly.
AWS API Gateway: synchronous integrations have a hard 29-second max. You cannot exceed it. Use async patterns if you need more time.
AWS ALB/NLB: idle timeout defaults to 60s; raise if you stream or expect slow reads.
Google Cloud Run: request timeout can be higher (up to many minutes), but keep client and proxy limits aligned.
Cloudflare/CDN workers: subrequest and CPU limits apply; stream or use queues for long work.
If your third-party supports a query parameter like timeout=50000, set it below the smallest upstream cap in your chain. If API Gateway caps at 29s, a 50s third-party timeout will never help.
Try once with a 6–8s timeout.
If it times out, retry with exponential backoff and jitter (for example, wait 300–700 ms, then 1–2s, then 2–4s).
Stop when the total budget is used.
Make sure the call is idempotent. For POST, use idempotency keys so the provider does not create duplicates.
Submit a job and return 202 Accepted with a job ID.
Let the provider call a webhook when done, or let the client poll a status endpoint.
Store partial results so you can resume after failures.
Ask for a smaller page size. Fetch more pages in parallel if allowed.
Stream results as chunks so proxies see activity and do not close the idle link.
Use ETags and If-None-Match to avoid re-downloading the same data.
Cache recent successful results for a short time (for example, 5–15 minutes) to mask brief slowness.
Show last known data with a “Refreshed X minutes ago” note if live data is late.
Set circuit breakers. When error rate or latency spikes, open the breaker and serve cached or fallback data.
DNS/connect timeout: 3–5 seconds. Keep it short to fail fast on bad hosts.
TLS handshake: 5–10 seconds if you must cross regions or mobile networks.
Read timeout per attempt: 8–20 seconds, depending on payload size and partner SLA.
Total time budget including retries: 15–30 seconds for user-facing flows. Longer for batch jobs.
Proxy read timeout: Slightly higher than your client read timeout to avoid the proxy cutting you off first.
If your third-party accepts a timeout parameter in milliseconds, match your per-attempt read timeout. For example, set timeout=15000 for a 15-second try.
Log per-call timings: DNS, connect, TLS, first byte, total time, bytes read, retries.
Emit metrics per partner: success rate, timeouts, p95/p99 latency, saturation of connection pools, queue size.
Set SLOs for each partner endpoint. Alert on error budget burn, not just raw failures.
Run synthetic checks from different regions and networks.
Chaos test: inject 2x–5x latency and see if your budget, retries, and breakers hold.
Confirm which layer timed out first (client, proxy, server, gateway, or third-party).
Align maximums: the smallest cap in the chain sets your true limit.
If a provider needs a query timeout (for example, timeout=50000), set it to your per-attempt read limit, not above your gateway cap.
Enable retries with jitter and a total time budget.
Add caching, streaming, and pagination to cut response time.
Watch logs and metrics. Adjust values based on p95/p99, not on hunches.
Client: 18s total budget, three tries (6s each) with jittered backoff.
Nginx: proxy_connect_timeout 5s, proxy_read_timeout 25s.
Third-party: timeout=6000 for each attempt.
Most calls finish on the first try in 3–5 seconds. A few slow ones retry once. Nginx never cuts off early, and your client never waits more than 18 seconds.
Raising limits blindly would have kept threads busy and hurt everyone. With budgets, retries, and the right proxy settings, you cut errors while staying fast.
Find the smallest clock in your call path. That is your real limit.
Increase limits where needed, but pair them with budgets, retries, and circuit breakers.
Prefer streaming, pagination, caching, and async flows over very long waits.
Measure everything. Tune based on real latency percentiles.
Done right, you now know how to increase third-party request timeout while guarding your app’s stability. Set the right values, add smart retries, and keep a tight time budget. Your users will see fewer errors and faster pages, even when partners slow down.
What a timeout error really means
A timeout is a clock. It stops a request when it takes too long. That clock can live in many places:How to increase third-party request timeout
Raising limits is simple, but you must do it in the right place. You want the smallest values that still meet your needs.At the HTTP client
Adjust connect and overall request timeouts so users do not wait forever.In your server code
Your server must wait long enough for upstream work, but not so long that it starves threads or event loops.Reverse proxies and web servers
Proxies often cause hidden timeouts. Make sure their limits exceed the client and app limits by a safe margin.API gateways and clouds
Gateways have hard caps. Know them before you raise anything else.Safer options than only raising the limit
Long waits can freeze threads, fill connection pools, and hurt all users. Pair larger timeouts with these patterns.Use a time budget and retry with backoff
Set a total budget for the whole operation, including retries. For example, 20 seconds. Then:Break long work into async jobs
If the upstream needs a long time, do not hold the user’s request open.Stream and paginate
Many timeouts happen when the response is big.Cache and fall back
Picking the right timeout values
Use data, not guesses. Start with these common ranges, then refine with latency percentiles (p50, p95, p99).Observability: see timeouts before users do
Measure, alert, and test under stress so you do not guess in the dark.Troubleshooting checklist
A quick example flow
Imagine you call a content parser that can take 2–12 seconds. Your app runs behind Nginx. You choose:Key takeaways
For more news: Click Here
FAQ
Q: What does “Request of third-party content timed out” mean?
A: A timeout is a clock that cancels a request when it takes too long, and that clock can exist in the HTTP client, your server or framework, a reverse proxy or gateway, or the third-party provider. If any of those clocks hits zero first the entire call chain fails and may return errors like 500 or 504.
Q: Which layers should I check before changing timeouts?
A: Check the HTTP client, your server/framework, any reverse proxy or gateway (for example Nginx or API Gateway), and the third-party provider because the smallest cap in the chain sets the true limit. Aligning these layers prevents one short timeout from canceling a longer one.
Q: Where is the right place to change timeouts to avoid breaking my app?
A: When learning how to increase third-party request timeout, change limits at the component whose clock is shortest and choose the smallest values that meet your needs while adding guardrails. Pair raised limits with budgets, retries, streaming, or async patterns so you do not starve threads or block event loops.
Q: What client-side timeout settings should I use for safe requests?
A: Adjust connect and overall request timeouts so users do not wait forever; examples from the guide include curl with –connect-timeout 5 and –max-time 20, fetch wrapped with AbortController aborting after 20,000 ms, and Axios with timeout: 20000. Keep a short connect timeout (for example 3–5s) and set read or total attempt timeouts in a sane range so sockets are not tied up.
Q: How should I configure proxies and gateways when increasing timeouts?
A: Make sure proxy and web server limits exceed your client and app limits by a safe margin; for example Nginx has proxy_connect_timeout, proxy_read_timeout and proxy_send_timeout and you might set connect 5s and read 60s for slow partners. Remember API gateways may impose hard caps (for example AWS API Gateway 29s) so set any third-party timeout parameter below the smallest cap in the chain.
Q: The third-party suggests adding a timeout query parameter; how should I use it?
A: If a provider supports a timeout query parameter in milliseconds, set it to match your per-attempt read timeout and ensure it is below the smallest upstream cap so it can take effect. Also include a total time budget and retries with backoff so a single long attempt does not block your app when learning how to increase third-party request timeout.
Q: What safer alternatives should I pair with increased timeouts?
A: Use a total time budget with retries, exponential backoff and jitter, and idempotency keys for non-idempotent operations, or convert long calls into async jobs with 202 Accepted and webhooks or polling. Also use streaming or pagination, caching and circuit breakers to avoid holding threads and to serve fallback data when partners are slow.
Q: How do I pick values and monitor timeout changes effectively?
A: Pick values based on real latency percentiles (p50, p95, p99) and start with common ranges such as DNS/connect 3–5s, TLS 5–10s, per-attempt read 8–20s, and a total user-facing budget of 15–30s, then refine with metrics. Instrument per-call timings, emit partner metrics, set SLOs, run synthetic checks, and chaos test latency to see if budgets and breakers hold.
* The information provided on this website is based solely on my personal experience, research and technical knowledge. This content should not be construed as investment advice or a recommendation. Any investment decision must be made on the basis of your own independent judgement.
Contents